Products
Solutions
Hardware
GPU servers, spares and integration - procured, built, commissioned.
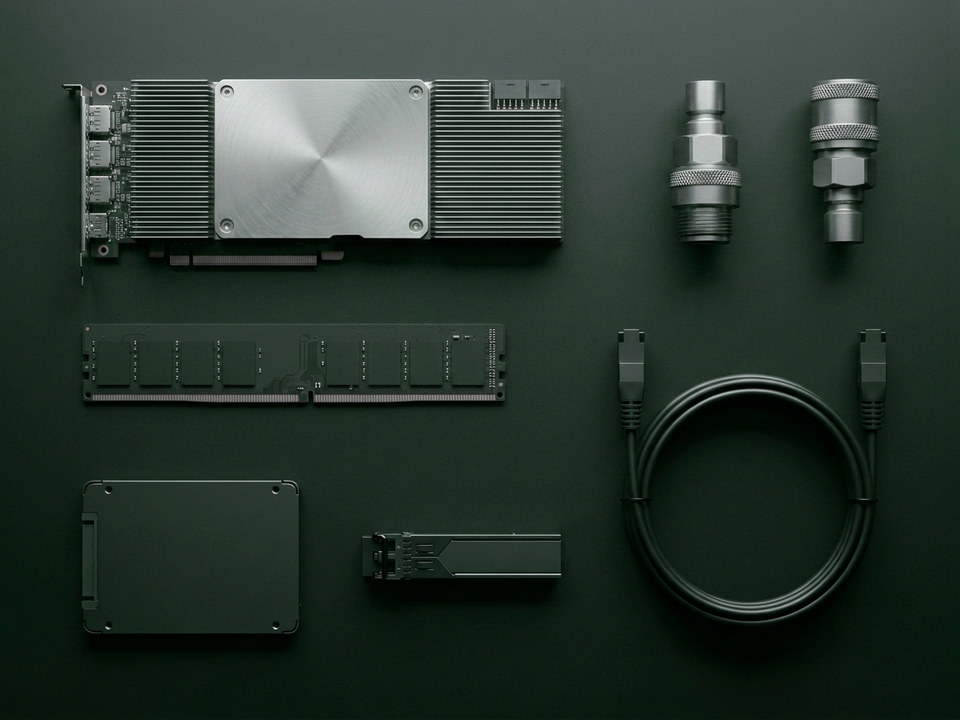
From silicon to commissioning
GPU servers, spares and integration - procured, built, commissioned.
Explore hardware →Company
Sovereign GPU cloud and infrastructure, built and operated in the Kingdom.
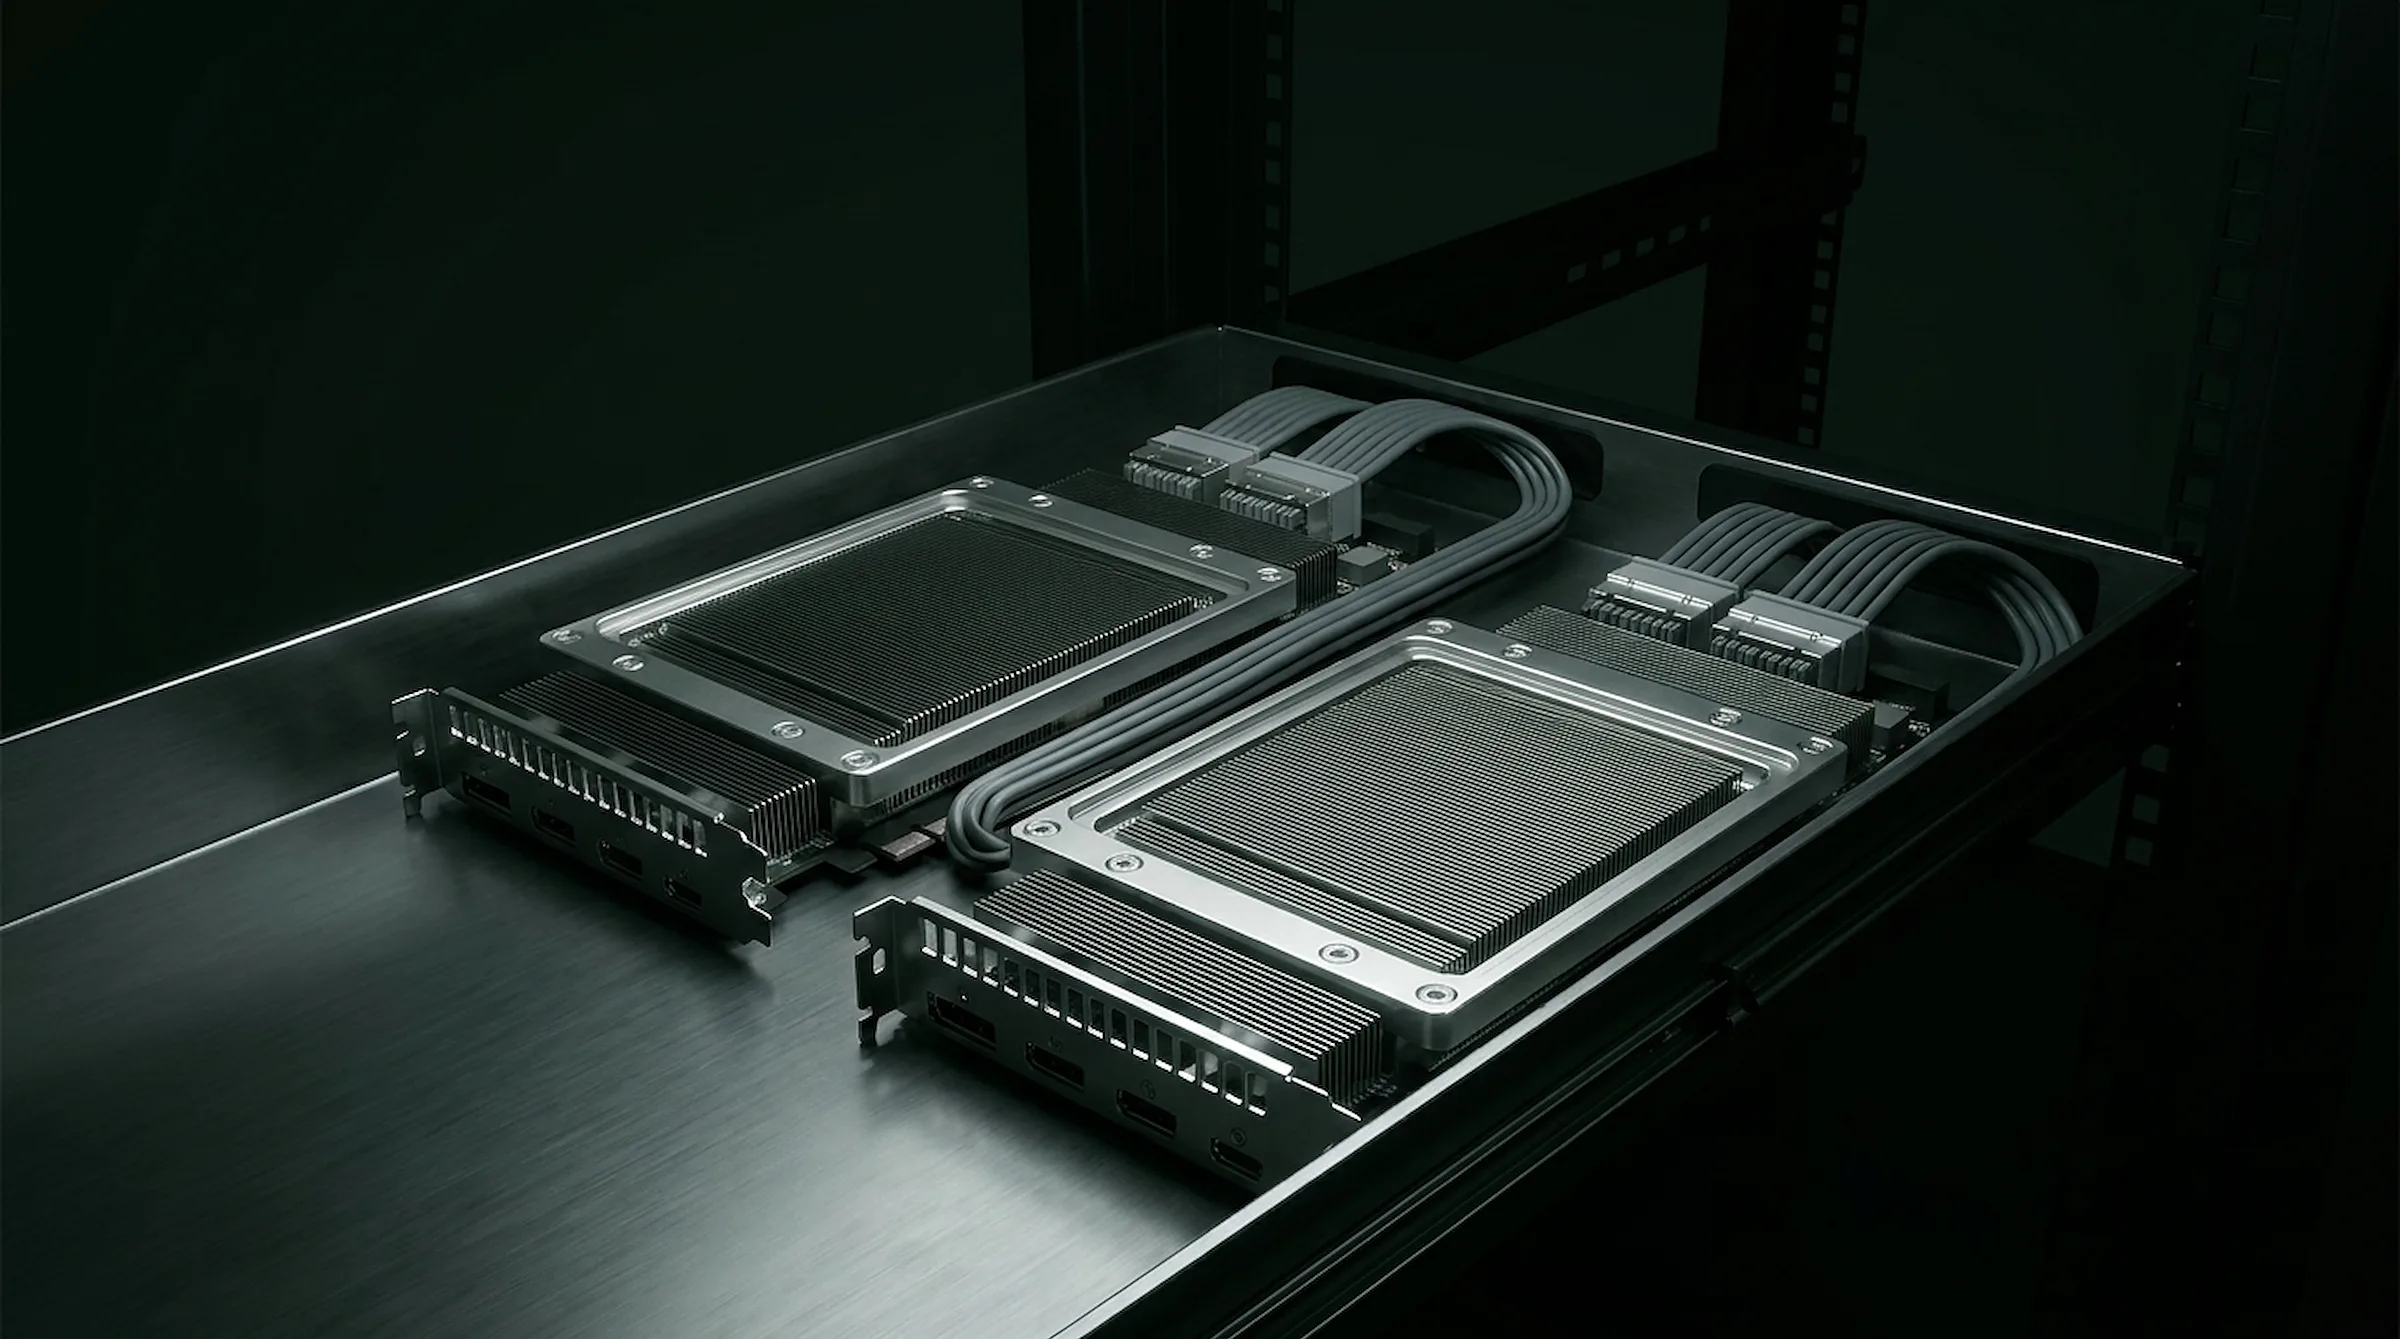
Proven at production scale.
H100 and H200 capacity - the workhorse fleet of the Kingdom's AI builders.
Get Hopper capacityThe workhorse of production AI.
Training, fine-tuning and serving on the most proven accelerator generation in the fleet.
- Mature CUDA, NCCL and Triton software stack
- Bare metal, virtual machines or managed clusters
- InfiniBand fabrics ready for multi-node training
HGX Board - NVLink All-to-All
Memory headroom for longer context.
The same Hopper architecture with a larger, faster memory system - built for long-context inference and heavier batches.
- More room per GPU for models and KV cache
- Drop-in for existing Hopper workloads
- Same stack, same fabrics, more headroom
HBM3e Stacks Beside the Die
H100 - Memory
0GB HBM3
H100 - Bandwidth
0TB/s
H200 - Memory
0GB HBM3e
H200 - Bandwidth
0TB/s
Get Hopper capacity.
Tell us what you run - we will shape H100 and H200 capacity around it.
Get Hopper capacity