Products
Solutions
Hardware
GPU servers, spares and integration - procured, built, commissioned.
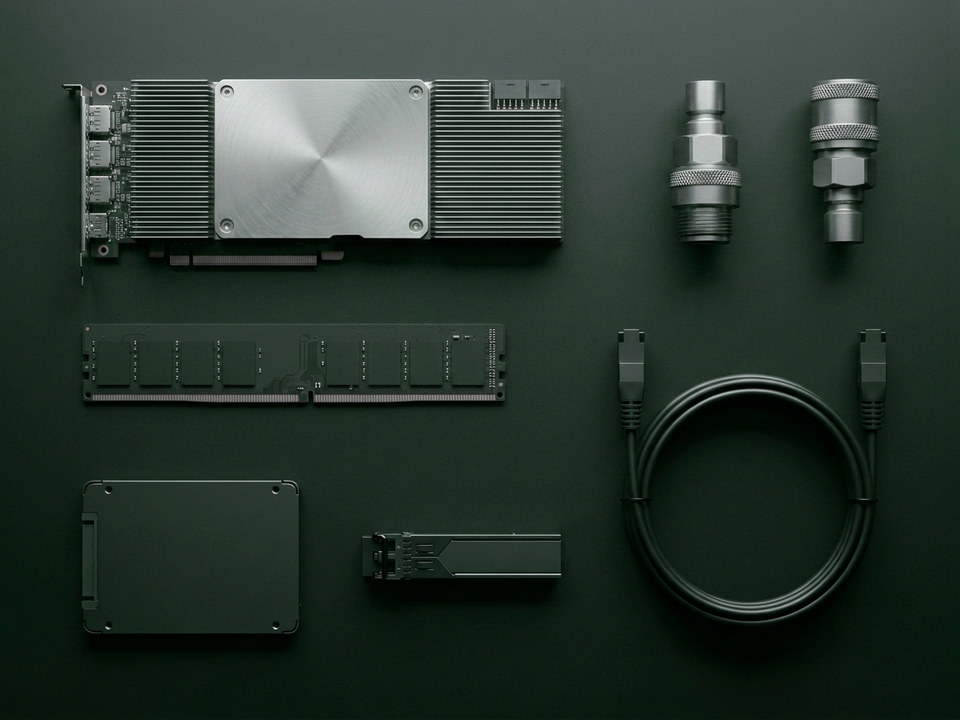
From silicon to commissioning
GPU servers, spares and integration - procured, built, commissioned.
Explore hardware →Company
Sovereign GPU cloud and infrastructure, built and operated in the Kingdom.
GPU Cloud
NVIDIA H100, H200, B200 and B300 capacity inside the Kingdom - by the hour, by the month, or dedicated to you.
Available GPU Models
From Hopper to Blackwell Ultra. Pick the memory footprint and bandwidth your workload needs - provisioned on demand, no procurement cycle.
NVIDIA Hopper
- Memory80 GB HBM3
- Bandwidth3.35 TB/s
- Memory141 GB HBM3e
- Bandwidth4.8 TB/s
NVIDIA Blackwell
- Memory192 GB HBM3e
- Bandwidth8 TB/s
- Memory288 GB HBM3e
- Bandwidthcontact for availability
Non-Blocking GPU Fabric
Every accelerator sits one hop from every other across a rail-optimized spine. No oversubscription, no contention - just line-rate collective bandwidth for training at pod scale.
Consumption Models
Match your commitment to your workload - burst on-demand, reserve committed capacity, or run a private cluster behind your own perimeter.
- Per-hour billing
- Self-serve via Launchpad
- Scale to zero
- 1-36 month terms
- Priority capacity
- Committed-use pricing
- Private bare-metal clusters
- Custom SLA
- Your security perimeter